Feature Retention Curves at the Individual User Level
Individual-level curves reveal why users leave, not just that they do.
A retention curve built from a whole cohort can tell a team that engagement fell. It cannot tell them who stopped, when they stopped, or why, which is the information a team actually needs to do anything about it. That gap sits at the center of how most B2B SaaS and PLG teams read their own data, and it costs them the one thing a retention curve is supposed to produce: a reason to act.
The problem starts with what gets averaged together. A single cohort curve blends three completely different populations into one line: users who adopted a feature deeply and never left, users who touched it once and vanished, and users who never tried it at all. The resulting average describes none of them accurately. A team looking at a declining cohort curve has no way to tell whether it's watching a mass exodus of former power users or a steady trickle of people who never got past their first session.
The same blending problem explains why cohort-level comparisons work so well for one purpose and fail so badly for another. Comparing retention curves across cohorts is a legitimate way to test whether an onboarding change or product update shifted behavior, because the comparison holds the population constant and varies the treatment. Collapsing everything into a single curve with no segmentation underneath it erases that power, because that collapse blends the distinct populations back together and produces the same undifferentiated average the comparison was designed to avoid.
Two users in the same cohort can have identical cohort-level retention contributions but completely different individual curves: one who used the feature every week and one who used it once in week one and never again both register as "retained" in month-one aggregate counts if the window is wide enough.
The timing compounds the problem. A typical B2B SaaS retention curve drops steepest in the first months after onboarding, stabilizes through the middle stretch, and flattens out among customers who've stuck around. At the feature level, that same three-phase pattern of discovery, habit formation, and abandonment occurs again, compressed into weeks instead of months. A blended, aggregate view moves too slowly to catch a window that narrow. By the time a cohort-level curve shows a dip, the users who drove it may have gone quiet weeks earlier.
What a retention curve built for a single user measures
A retention curve built for one person plots whether that specific individual returned to a specific feature at each measured interval after they first used it. It's a behavioral time series for a single user, a different kind of measurement than a statistical summary drawn from many.
The math is the same formula teams already use at the cohort level: users active at time T divided by users in the starting cohort. At the individual level, that cohort collapses to one person, and the curve tracks their state at Day 7, Day 30, Month 3, Month 6, Month 12, and beyond. Nothing about the formula changes. What changes is the resolution.
Before any of that math means anything, a team has to define what "active" means for the feature in question. Logging in is not the same signal as performing the key action the feature exists to support, and that definition of meaningful engagement is the actual retention criterion a curve measures against.
Two users in the same cohort can have identical cohort-level retention contributions but completely different individual curves: one who used the feature every week and one who used it once in week one and never again both register as "retained" in month-one aggregate counts if the window is wide enough. One of them opens the feature every week without fail. The other opens it exactly once, in week one, and never again. Measured at the cohort level with a wide enough window, both of them register as "retained" in the month-one count. Their individual curves look nothing alike, but the aggregate number treats them as identical data points. That single example is the clearest argument for building retention curves at the individual level at all: the aggregate number is mathematically correct and behaviorally meaningless.
Individual-level tracking also makes it possible to separate what a person is doing from what an account is doing, and in B2B SaaS that distinction matters enormously. An account can look fully retained because one power user keeps logging in and keeps the account's usage metrics alive, while every other seat holder on that account has a curve that flattened out in week two. Account-level retention and person-level retention are different measurements, and conflating them hides seat-level abandonment that later causes a renewal risk nobody saw coming.
Building individual-level feature retention curves from data a team already has
Building a retention curve for each user doesn't require a new tracking plan or a new instrumentation layer. It requires two things most B2B SaaS teams already have sitting in their systems: a record of who is eligible to use a given feature, and a log of whether each of those people actually used it at each measured interval.
The first decision, and the one most likely to get it wrong, is choosing the denominator. The correct denominator is the set of users who had access to the feature and a real reason to use it, not every user in the product. Picture a feature gated to a specific plan tier. If a team measures adoption against the full user base, including users who could never have touched the feature in the first place, the adoption rate looks artificially low and the retention curve built on top of it is distorted from the start. Getting the eligible cohort right is a prerequisite.
Once the eligible cohort is defined, several signals, tracked per user at each interval, do most of the work. First use establishes whether a person ever triggered the feature's key action. Repeat use checks whether they triggered it again in the following period, whether that's the next week, the next workflow cycle, or the next month. Sustained use asks whether they're still triggering the action at Month 3 and Month 6. Depth asks whether they're sticking to the feature's basic path or progressing into its more advanced capabilities.
None of this requires new data collection, because the two inputs already exist in different places. The backend database holds current state: who the user is, what plan they're on, what role they hold, and which features are enabled for their account. Product analytics holds behavioral history: what they did, when, and how often.
Turning that into a working curve follows a sequence that any team can sketch for itself. Start by defining the key action for the feature, the one action that demonstrates its core value rather than a page view that demonstrates nothing. Identify the eligible cohort: users with access, on a plan where the feature is live, in a role where it's relevant to their work. Record each user's first-use date as the starting point of their individual curve. Query their activity log at Day 7, Day 30, Month 3, and Month 6 to plot the shape of that curve. Then flag any user whose curve breaks, with no repeat use after the first touch, as a distinct population from users who never started at all and users whose use has sustained.
The three distinct curve shapes individual retention data reveals
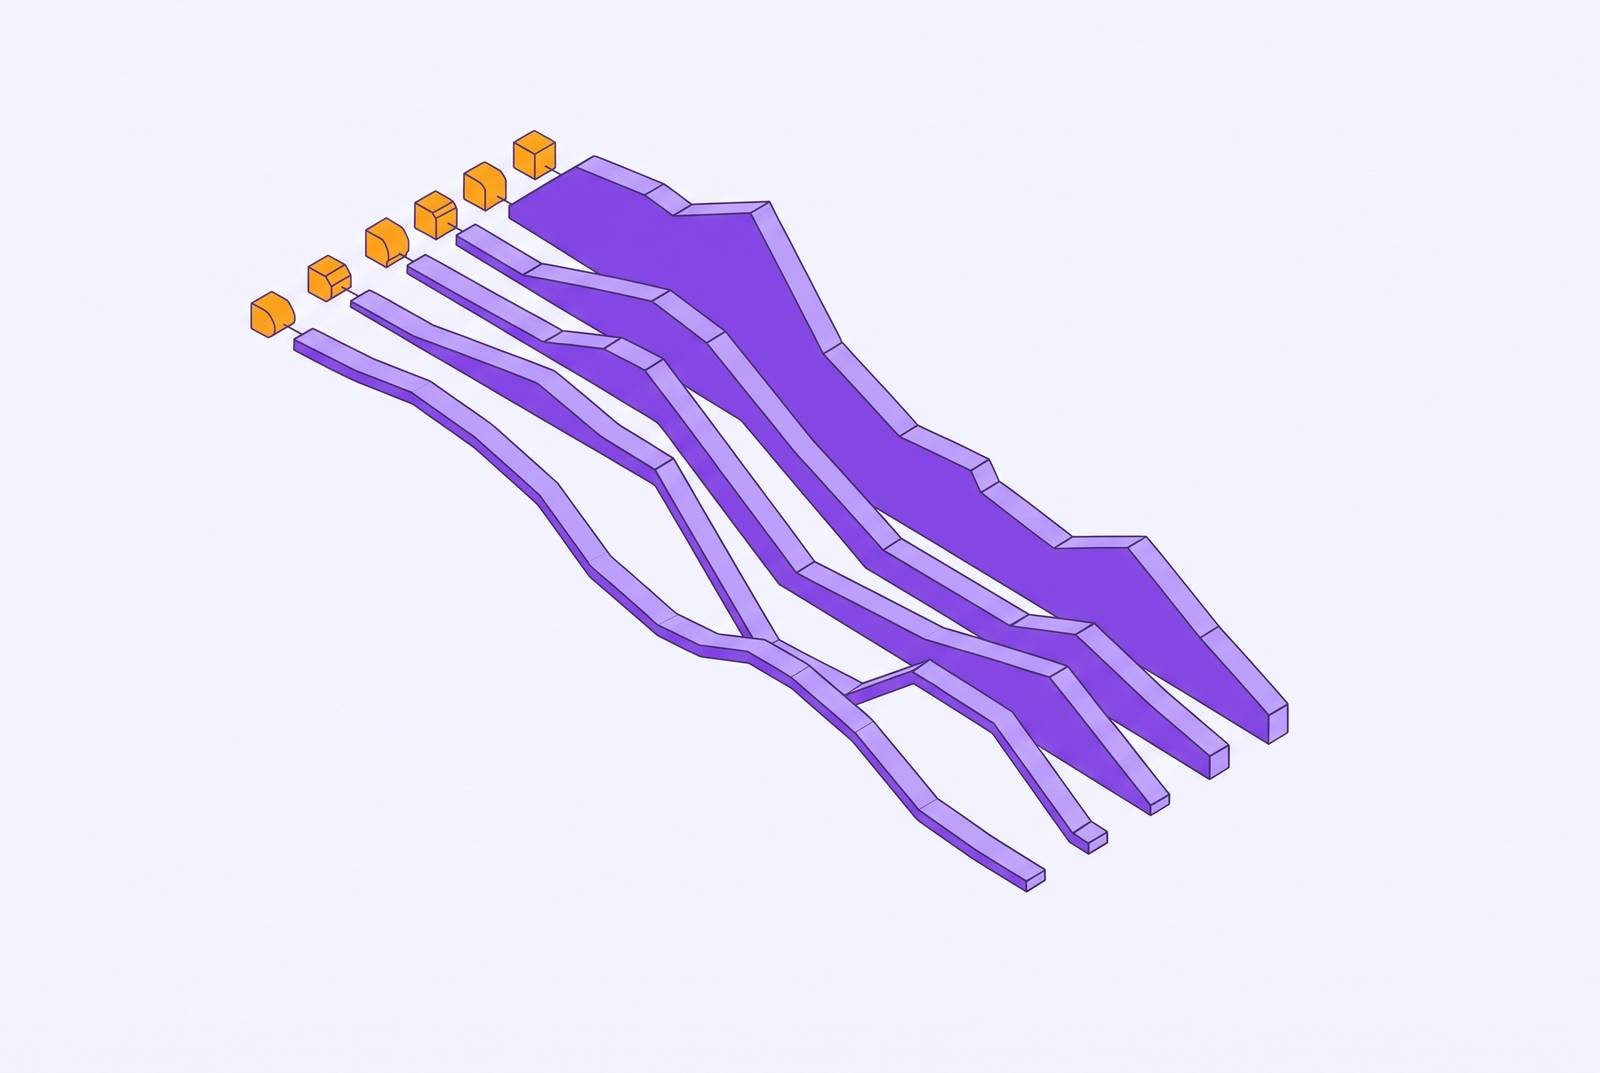
Once curves are built at the individual level, users stop looking like points on a single declining line and start sorting into a small number of distinct behavioral shapes. Each shape names a different failure mode or a different success pattern, and the aggregate curve buries all of them under one average.
The first shape is the early-drop curve: a user tries the feature once and never repeats the key action within the expected workflow cycle. This is the zombie-user pattern, someone who got exposed to the feature, poked at it once, and left for good. An aggregate curve shows this only as a small drag on the overall average. An individual curve names exactly who did it and the precise moment their engagement broke. The scale of this pattern is larger than most teams assume: industry analyses estimate that 40 to 60 percent of free users never reach activation at all, and among those who do activate, a meaningful share never return. An aggregate curve renders that as a smooth, gradual decline. The individual data shows a discrete group of people who all stopped at roughly the same point in their journey.
The second shape is the delayed-habit curve. A user tries the feature, goes quiet for days or weeks, then comes back for a second and third use that stabilizes into a regular pattern. This person simply took longer than others to fold the feature into their actual workflow, and eventually did. Looked at through a week-two aggregate lens, this user looks like a churn risk. Looked at through an individual curve, the gap is part of a habit forming on a slower cycle. Treating this shape the same as early-drop means burning a re-engagement message on someone who didn't need it, and doing that repeatedly erodes the credibility of every message that follows.
The third shape is the sustained-use curve: repeat use at or above the expected cadence for that workflow, holding steady through Month 3 and beyond. These are the individual curves that flatten out at a high retention rate, and they're valuable for more than celebrating a win. Cohort-based retention analysis already shows that users who complete specific activation milestones and adopt certain combinations of features retain at substantially higher rates. Reading individual curves lets a team work backward from a shape-three user to the specific sequence of actions that produced it.
A fourth pattern, the seat-split, is distinct enough to matter on its own in multi-user B2B accounts: an account can register as shape three at the account level purely because one power user dominates its usage log, while most of the other seat holders on that same account show shape one. Account-level retention metrics hide this completely. Individual curves are the only way to see it.
The value of sorting users into these shapes is that each one calls for a different response. A team no longer has one declining cohort number and one generic message to send everyone in it. An early-drop user needs something concrete, tied to what they actually did during their one attempt. A delayed-habit user, reading the same declining cohort number, may need no intervention.
Which features are worth building individual retention curves for
Building a per-user retention curve for every feature in a product sounds thorough, but it produces the opposite of clarity. It creates signal noise that makes acting on the data harder, not easier, so the first real question is where to point these curves.
Most B2B SaaS products have a large number of distinct features, but users regularly engage with only a small core subset of them. The rest sit largely unused, and building individual curves for a feature nobody touches produces data too sparse to separate a real pattern from random noise.
The test for where to invest is a direct comparison. Take the aggregate retention curve of users who adopted a given feature and set it against the aggregate curve of users who never touched it. If the two curves sit close to identical, meaning adopters and non-adopters retain at roughly the same rate, the feature is a nice-to-have rather than a retention driver, and individual-level tracking on it is effort spent in the wrong place. If the two curves diverge meaningfully, with adopters retaining at a clearly higher rate than non-adopters, the feature earns a place on the list of candidates for per-user tracking and intervention.
That divergence test lines up with the shape-based classification from the previous section rather than contradicting it. The features that show up repeatedly in the behavioral histories of shape-three, sustained-use users tend to be the same features that show the biggest adopter-versus-non-adopter divergence at the cohort level.
Account-level adoption depth adds a third data point. Accounts that use a broad set of core features retain at rates far above accounts that lean on only one or two. The features worth tracking at the individual level aren't just the ones used most by the highest-retaining individuals, they're the ones that show up in the adoption paths of the highest-retaining accounts as a whole.
Put together, this becomes a short, repeatable prioritization process. Run the adopter-versus-non-adopter cohort comparison for every candidate feature. Rank features by how far apart those two curves sit. Build individual-level curves only for the features at the top of that ranking, the ones where adoption demonstrably predicts retention rather than merely correlating with it. Revisit that ranking as the product evolves, because a new feature shipped without running this comparison is a feature released with no evidence at all about its contribution to retention.
What individual retention curves reveal that triggers meaningful intervention
None of the classification work matters unless it connects to a specific action for a specific person at the moment that action is most likely to change their behavior. A broadcast message sent to everyone in a declining cohort is not that action, no matter how well-intentioned.
The early-drop signal carries a narrow window. Research on activation points to days 3 through 7 after first use as the highest-leverage moment for intervention, because behavior in those first days predicts both whether a user reaches activation at all and whether an activated user comes back. Past that window, bringing a dormant user back gets more expensive and less likely to work. A team that waits for an aggregate curve to show a decline has already missed this window by the time the dip is visible.
The delayed-habit signal calls for the opposite response: restraint. A user whose individual curve shows a gap followed by a second and third use is not at risk, and reaching out during that gap mistakes a normal behavioral pattern for a problem that doesn't exist. That contact doesn't just fail to help, it spends a touchpoint on someone who was already correcting course on their own, and it's exactly the kind of message that teaches users to ignore the next one. Checking a user's individual curve before deciding whether to intervene, rather than acting on their cohort's declining rate alone, is what keeps a retention program targeted instead of noisy. The shape of one person's curve, read on its own, tells a team whether to act now, act differently, or hold off.